New
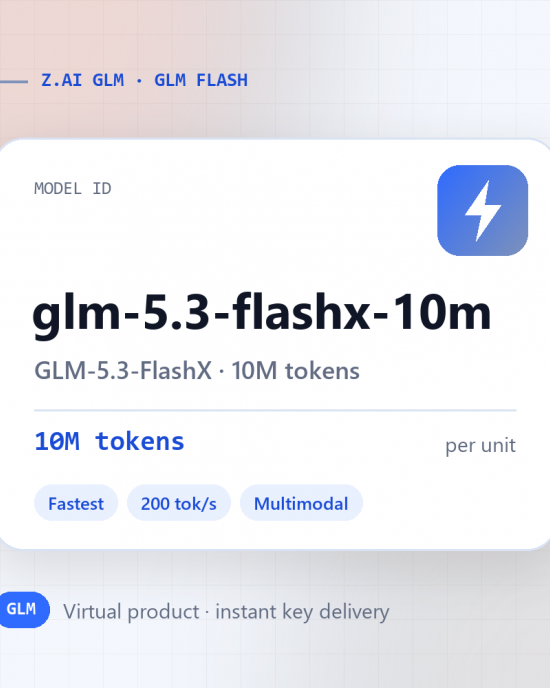
GLM-5.3-FlashX · 10M tokens
The same capability profile as Flash, tuned for inference speed at around 200 output tokens per second, for interfaces where perceived latency matters.
What you get
- 10M tokens for every unit you buy. Order several units to stack quota.
- A personal access key for
glm-5.3-flashx, issued automatically once your order is completed. - No shipping: delivery is digital, under My Account > Order History and by email.
Capabilities
- Fastest
- 200 tok/s
- Multimodal
- 1M context
Best for
Latency-sensitive agents and interactive multimodal tools.
Quick start
from zai import ZaiClient
client = ZaiClient(api_key="YOUR_ACCESS_KEY", base_url="YOUR_BASE_URL")
response = client.chat.completions.create(
model="glm-5.3-flashx",
messages=[{"role": "user", "content": "Hello"}],
reasoning_effort="max",
)
print(response.choices[0].message.content)
| Model Specs | |
| Model ID | glm-5.3-flashx |
| Context Window | 1M tokens |
| Max Output | 128K tokens |
| Modalities | Text, image in / text out |
| Capabilities | Fastest, 200 tok/s, Multimodal, 1M context |
| Best For | Latency-sensitive agents and interactive multimodal tools |
| Unit Size | 10M tokens |
- Stock: In Stock
- Model: glm-5.3-flashx-10m
- SKU: GLM-5.3-FLASHX-10M
Products Sold: 0
Product Views: 30
$12.50
10 or more $11.88
50 or more $11.25
Virtual product
Instant digital delivery · No shipping
- API model:
glm-5.3-flashx - Each unit: 10M tokens
Your access key is issued automatically once payment is completed and appears under My Account > Order History.